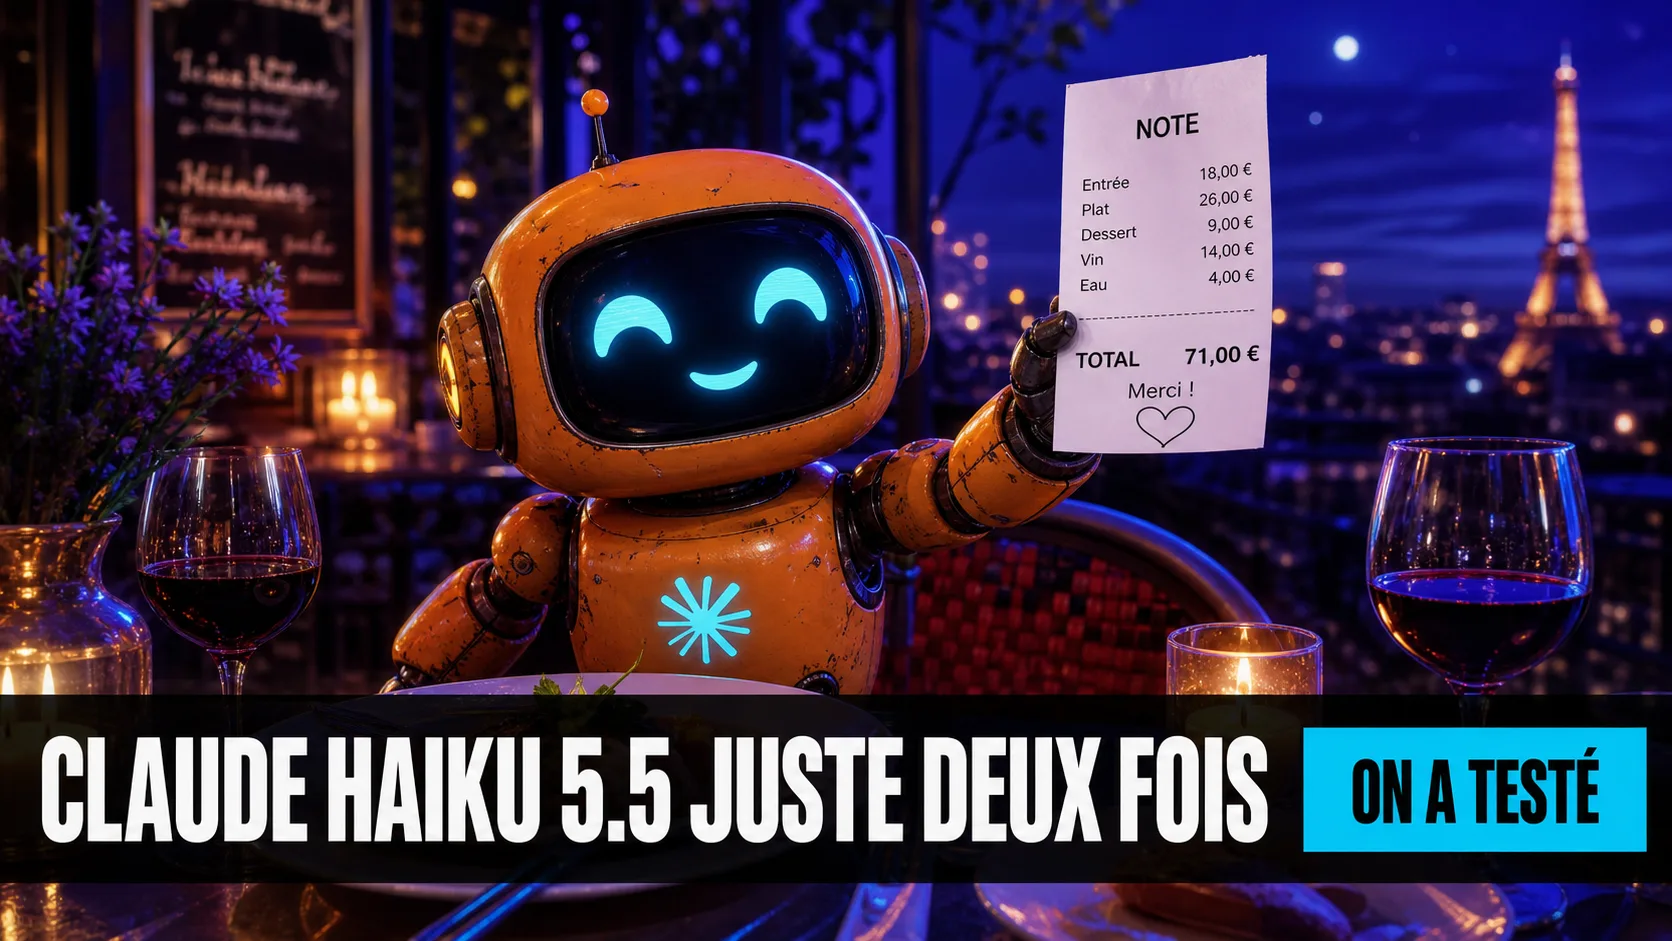
187.40 euros, five diners, three desserts at 8 euros. That bill tripped up free GPT-6 twice in a row. We put it as is to Claude Haiku, Anthropic’s small model, on October 13. The answer was right on the first try, check included. What’s left is the topic that got people talking all week, its price, and there the advertised figure doesn’t tell the whole story.
Claude Haiku facing the same bill as GPT-6
A word on method, because it differs from the previous test. The free GPT-6 test was done in ChatGPT, without an account. This one was done in Claude Code (Anthropic’s developer tool), set to the Haiku 5.5 model, around 3:25 pm, with the instruction to use no tools (no calculator, no search). It is neither the consumer claude.ai app nor a free account. Two questions, one attempt each: this is a one-off test, not a benchmark (a series of repeated, comparable measurements).
First question, word for word the one GPT-6 got: the 187.40 euro bill for five, three of them with a dessert at 8 euros. Below is Haiku 5.5’s reply, reproduced verbatim, in French, the language of the test.
Claude Haiku 5.5’s answer, October 13, 2026, full text
Si les 187,40 € incluent les desserts, chacun des trois qui ont pris un dessert paie 40,68 €, et les deux autres paient 32,68 €.
Le calcul : 3 desserts × 8 € = 24 €. Il reste 187,40 − 24 = 163,40 €, partagés entre les 5 personnes : 32,68 € chacune. Ceux qui ont pris un dessert ajoutent 8 €, soit 40,68 €. Vérification : 3 × 40,68 + 2 × 32,68 = 187,40 €.
Si les desserts étaient ajoutés en plus des 187,40 € (l’addition ne les incluait pas), le total serait de 211,40 € : chacun paierait 37,48 €, et ceux qui ont pris un dessert paieraient 45,48 €.
The amounts are right: 32.68 euros for the two without dessert, 40.68 euros for the other three, and the sum does come back to 187.40 euros. Haiku also spotted an ambiguity in the question on its own: are the desserts already in the bill, or added on top? It handles both cases. The second calculation holds up too, with a total of 211.40 euros, 37.48 euros per person and 45.48 euros for the dessert eaters.
The 1% mount, and an English word that wandered off
Second question, the mount that drops from a boss at a 1% chance, at 100, 200, 300 and 500 kills, then the number of kills needed to reach a 90% chance. The reply below is again reproduced verbatim, in French, the language of the test.
Claude Haiku 5.5’s answer, October 13, 2026, full text
Ta chance d’avoir obtenu la monture au moins une fois se calcule ainsi : chaque kill a 99 % de chances de ne PAS la donner, donc après n kills la chance de ne jamais l’avoir est 0,99 puissance n. La chance d’au moins une monture est donc 1 – 0,99^n.
- 100 kills : environ 63,4 % de chances
- 200 kills : environ 86,6 % de chances
- 300 kills : environ 95,1 % de chances
- 500 kills : environ 99,3 % de chances
Pour atteindre 90 % de chances, il faut environ 230 kills (229 kills donnent 89,98 %, 230 kills donnent 90,07 %).
Ces chiffres supposent que chaque kill est indépendant et que le taux de 1 % est exact. Il s’agit de probabilités, pas de garanties : certains joueurs auront la monture dès les premiers kills, d’autres after plus de 500.
Every figure is correct: 1 minus 0.99 to the power of 100 does give 63.4%, and the 90% threshold lands at 230 kills (the exact calculation gives 229.1). One detail closes the picture: the word “after” (highlighted in the box) slipped into the last sentence, an English word in the middle of a French answer. We did not fix it in the box. Another difference from GPT-6: Haiku answers in plain text, with no interactive interface or chart. So it has no fancy tool to show off and no curve to get wrong.
The price of Claude Haiku 5.5, tokens included
Anthropic released Haiku 5.5 on October 7. On its announcement page, the API (the access developers use to plug the model into their own programs) charges $0.10 per million input tokens and $0.50 for output, for requests up to 100,000 tokens, against $1 and $5 for Haiku 4.5. A token is the unit of text the model reads and bills: a word counts as one or more tokens. Beyond 100,000 tokens, the rate rises to $0.50 and $2.50. Anthropic advertises “roughly 75% cheaper” on average and specifies that 90% of Haiku 4.5 requests stayed under 100,000 tokens.
The rate per token doesn’t tell the whole story. At ComputingForGeeks, Josphat Mutai notes that the new tokenizer (the splitter that turns text into tokens) counts the same text as roughly 30% more tokens than before. His measurements range from 1.11 times for JSON to 1.36 times for English prose. The site MetricNexus gives the same order of magnitude and works out the vendor’s math from it: 30% more tokens against a price cut by ten, about 74% net savings on the average bill.
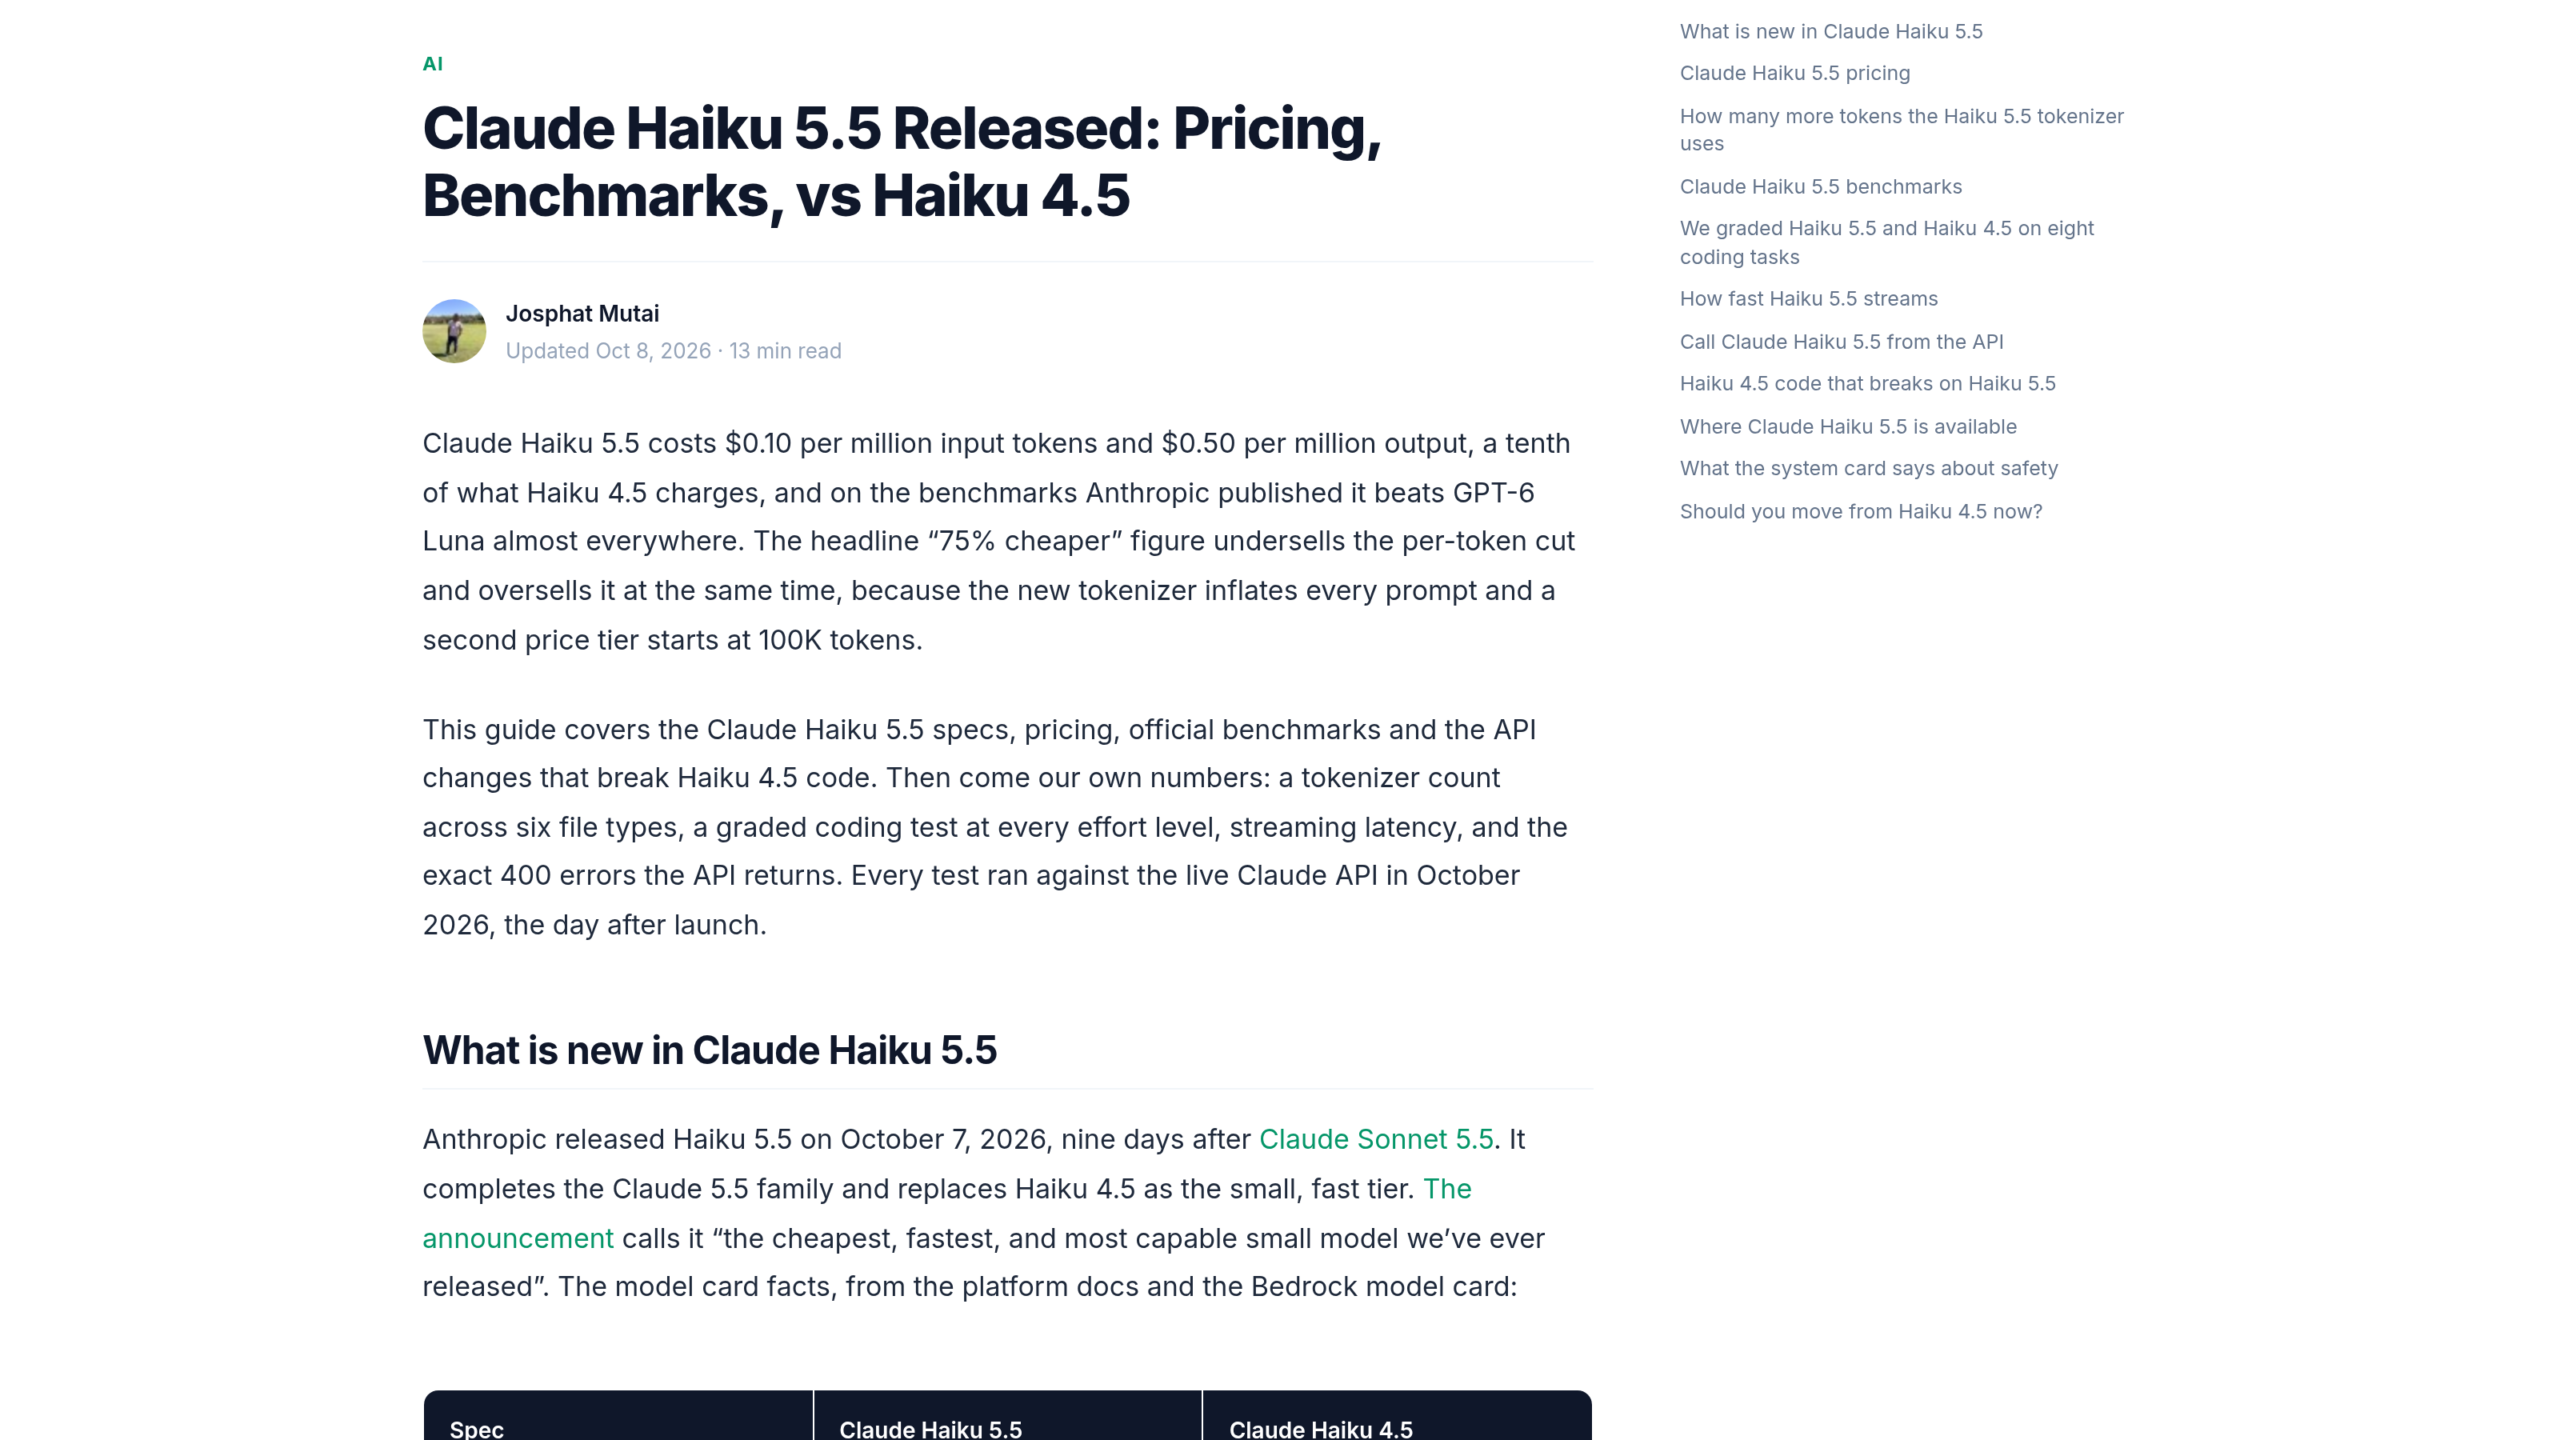
Let’s run the numbers for a text that cost one million tokens on Haiku 4.5. On version 5.5, it weighs about 1.3 million. At $0.10 per million input tokens, that comes to $0.13 instead of $1: 87% less, not 90%. Same ratio on output, $0.65 instead of $5. Above 100,000 tokens, the conclusion changes: 1.3 million tokens at $0.50 cost $0.65 instead of $1, only 35% less. ComputingForGeeks prices two cases at the public rate: a 20,000-token prompt with a 1,000-token reply goes from $0.025 to $0.0033 (87% savings), a 150,000-token prompt from $0.16 to $0.104 (35%).
The trap hides at the boundary: the 100,000 tokens are counted with the new tokenizer. A prompt of around 80,000 tokens on Haiku 4.5 can therefore cross the line and move to the rate five times higher, and that rate applies to the whole request. For a reader who only sends short questions, the drop stays massive. For one who loads big documents, it melts away.
What Haiku’s benchmarks are worth
A benchmark is a standardized test used to compare models. The ones Anthropic cites come from the vendor and are not independently verified. According to figures relayed by ComputingForGeeks, Haiku 5.5 reaches 72.4% on OSWorld (tasks to carry out on a computer), against 15.7% for Haiku 4.5, and 1,620 on GDPval (a ranking of professional work), against 735. The same site notes that Artificial Analysis measured 33% on Terminal-Bench where Anthropic claims 39.2%.
The independent measurement comes from Artificial Analysis, which ranks models on its Intelligence Index. Haiku 5.5 scores 43 at maximum setting there, ahead of Gemini 3.8 Flash (41) and GPT-6 Luna (38), the free model we tested. This ranking is repeated by Tech Jacks Solutions, which keeps the vendor-claim label on Anthropic’s figures. According to MetricNexus, that setting uses about 162,000 output tokens per task, three times GPT-6 Luna: the real bill also depends on that wordiness.
A thrifty model is only worth it if it rarely gets things wrong. On our two questions, Haiku made no mistake, where GPT-6 had made two, which is thin ground for concluding anything. Anthropic’s models are not infallible either, as a false murder report sent by Claude to the police showed last week. On price, the useful comparison is not Haiku 5.5 against the sticker, but your own bill, calculated with 30% more tokens.
0 Commentaires
Aucun commentaire pour le moment. Soyez le premier à commenter !